SEO, GEO and the CMS on one autopilot.
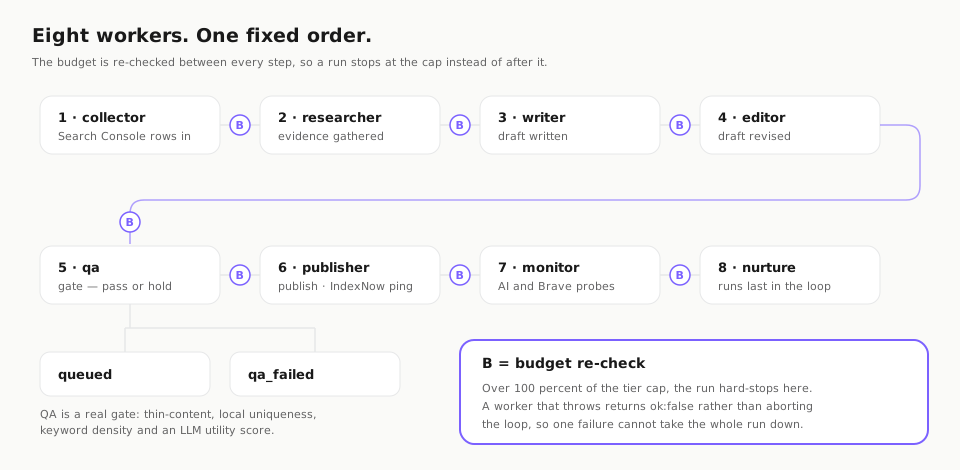
Eight workers, and a budget gate between each.
Most “AI content” tools are one long prompt with a progress bar. Growzo is a pipeline of eight named workers that run in a fixed order, each one handing a defined artefact to the next: rows become evidence, evidence becomes a draft, a draft becomes a revision, and only then does anything reach a gate. Because the stages are separate, a failure is attributable — you can see which worker stopped and why, instead of watching a single opaque call return nothing.
| # | Worker | What it does |
|---|---|---|
| 1 | collector | Pulls Search Console rows, idempotently |
| 2 | researcher | Gathers the evidence a page will cite |
| 3 | writer | Drafts against that evidence |
| 4 | editor | Revises the draft |
| 5 | qa | Gates it — pass to queued, or qa_failed |
| 6 | publisher | Publishes, then pings IndexNow |
| 7 | monitor | Probes AI engines and Brave SERP |
| 8 | nurture | Runs last in the loop |
ok:false and the loop continues — one bad page does not cost you the other seven stages.QA is a gate, not a rubber stamp.
A generator that publishes everything it writes is a scaled-content machine, and Google has a policy for those. Growzo’s QA worker sits between the editor and the publisher and can refuse: it applies four independent checks and routes the page either to queued or to qa_failed. Nothing skips it, and nothing is published on a maybe.
Thin content
The oldest failure mode in programmatic publishing: a page too slight to deserve an index entry. Growzo measures it before publishing rather than discovering it in a coverage report three months later.
Local uniqueness
A Jaccard comparison against your own existing pages. The question it answers is the one that actually gets sites penalised: is this page interchangeable with a sibling that already exists, with a noun swapped?
Keyword density
Density in a band, not a target. Over-optimisation is as detectable as under-, and a draft that repeats its phrase to hit a number reads exactly like one.
LLM utility score
A model is asked whether the page is actually useful to a reader. It is the only one of the four that no regular expression can approximate, which is why it is scored separately rather than folded into the others.
SEO, AEO and GEO, scored on every save.
Scores are written append-only on every save and denormalised for sorting, so a page carries its own history rather than one number that quietly changed. Three separate scores, because the three jobs are genuinely different: ranking a page, getting one passage lifted as an answer, and getting the page cited by a model are not the same problem. Empty pages are deliberately left unscored — a zero for a page nobody has written yet is noise.
SEO — the classic surface
Yoast-parity on-page assistance with explicit thresholds: a title is good to 60 characters and bad past 70, a meta description good to 160 and bad past 200. Schema is generated for you as Article plus BreadcrumbList, with FAQPage added when the page has FAQs and a Person author carrying credentials and sameAs. A malformed author block cannot take the generated nodes down with it.
AEO — can one passage be lifted?
An answer engine quotes a passage and deep-links it. AEO scoring asks whether that is possible here — and includes stable-anchor detection: a positional id like section-3 is flagged, because when the page grows a section the cited deep link silently drifts to different text and nobody is told.
GEO — is there anything to cite?
GEO measures evidence density, original-claim language, how many real statistics the page carries, how many sources it names, and whether it contains self-contained passages of roughly 40 to 120 words. Those are the units a model can quote and be correct about. More on the GEO tier.
Who arrived, what they did, what fought them.
Search Console, GA4 and Microsoft Clarity each answer a third of the question, and almost every stack keeps them in three tabs. Growzo joins them on the URL, so one row tells you the query that brought someone in, what they did once they landed, and where the page fought back.
| Source | The question it answers | Never connected | Connected, nothing to show |
|---|---|---|---|
| Search Console | Who arrived, and on what query | not_connected | no_data |
| GA4 | What they did once they landed | not_connected | no_data |
| Microsoft Clarity | What fought them on the page | not_connected | no_data |
Indexing that refuses to abuse the API.
Google’s Indexing API is documented as being for JobPosting and BroadcastEvent pages. Most “instant index” tools push everything through it anyway. Growzo refuses ineligible page types at the API boundary and records them as skipped, so your account is not the one holding the risk when that tolerance ends.
Overflow is queued, never dropped
Quotas are 200 a day for Google and 10,000 a day for IndexNow. Anything over the line is queued for the next day rather than discarded, so a busy publishing day does not silently lose submissions — the failure mode a queue exists to prevent.
The same posture in link building
Written into the product: nothing here places a link. It finds opportunities a human pursues. That is the difference between a research tool and an automated link scheme, and it is a difference worth being unambiguous about.
A Google connection that does not expire.
Paste a service-account JSON per project and the connection is done: no consent screen, no environment variables, no interactive sign-in for anyone to redo. Every OAuth-only tool running on an unpublished consent screen hits Google’s seven-day refresh token expiry, which is why so many SEO dashboards quietly stop collecting after a week and nobody notices until a month of data is missing.
Per project, not per person
A service account belongs to the project, so the data keeps arriving when the person who first connected it leaves, changes password or loses access.
Nothing in an env file
Credentials are entered in the app and scoped to the project that owns them, rather than baked into a deployment where one file governs every tenant at once.
Honest empty states
Any surface without real data behind it renders an explicit sample-data notice. The codebase enforces it as a doctrine, so a demo screen can never be mistaken for your numbers.
A real CMS underneath, not a posts table.
The autopilot has to publish somewhere, and bolting a generator onto someone else’s CMS is where most of these tools leak. Growzo ships its own headless CMS with a Strapi-compatible read API, so an existing front end can consume it without a rewrite — and importers that have been run against real installs, discovering 779, 768 and 1,127 entries with no hardcoded literals anywhere in the path.
Versioning, a TipTap editor, scheduled publishing, authors carrying sameAs, HMAC-signed webhooks, an IndexNow ping fired on publish, and an origin cache with prefix purge so a single edit does not force a full flush. It is the unglamorous half of the product, and it is the half that decides whether the interesting half can ship anything.
What Growzo does not do.
Growzo is pre-1.0 and open source, and this list is published because a buyer who finds a missing feature after paying for it has been misled, while a buyer who reads it here has been informed. Some of these were claimed by Growzo’s own older marketing copy; that copy was wrong, and this page is the correction.
Not eight AI engines
Four are probed. Copilot, Grok, You.com and Phind exist only as enum values with no prober behind them. Anything claiming eight is counting names, not measurements.
Not multi-engine rank tracking
Brave only. There is no Google, Bing, Yandex, Baidu, DuckDuckGo or Naver rank tracker, and no AI Overview detection — that field is a deliberate placeholder.
No backlink data
Growzo does the link maths — anchor buckets, over-optimisation and unnatural-velocity flags, a Google-format disavow file — but it discovers no links itself and reports no domain rating, toxicity data or live-versus-lost tracking.
No keyword volume or difficulty
Those numbers are not measured anywhere in the product, so they are not sold here. The real demand signal Growzo has is your own Search Console history.
No site-wide crawl
The AI-readiness audit samples a maximum of ten pages. There is no internal-link crawling, no orphan detection and no Core Web Vitals, Lighthouse or PageSpeed data.
No third-party SEO suites
No Ahrefs, Semrush, Moz or DataForSEO integration, and no Bing Webmaster Tools. There is also no scheduler daemon: an external cron drives collection.
The two tiers built furthest past this line are the ones worth reading next: AI crawler control and llms.txt delivery, and the hard money cap.
Growzo, answered plainly.
What does the Growzo autopilot actually do?
Which AI engines does Growzo probe, and how honest are the citations?
Does Growzo track rankings on Google and Bing?
How much of my site can Growzo audit?
Is Growzo a paid Autocloz subscription?
Does Growzo run itself on a schedule?
Run it yourself. Cap it yourself.
Growzo runs on its own application and its own sign-in — an Autocloz account is not required. It is open source, self-hosted and bring-your-own-key, so the only bill is the one you cap.